Skip to content
Browserbase
    • Primitives
      • BrowsersCloud browsers for your agent to use the web
      • AgentsScale fully managed browser agents with simple prompts
      • SearchFind relevant websites from a single query
      • FetchRetrieve web data as agent-ready HTML, JSON, or markdown
      • RuntimeScalable, sandboxed environments for agent deployments
      • IdentityAuthenticate your agent to navigate the web like a human
      • ModelsUse any model with a single API key
      • ObservabilityUnified debugging your agent across replays, logs, and prompts
    • Open Source
      • Browse CLIGive your agent browsing skills with a single command
      • StagehandThe most popular AI browser automation framework
    • Use Cases
      • Browser Agents
      • Automated Testing
      • Workflow Automation
      • Web Data Extraction
      All use cases
    • Industries
      • AI & Agent Platforms
      • Healthcare
      • Fintech
      • GTM
      • Legal
    • Resources
      • Blog
      • Customers
      • Enterprise
      • Templates
  • Pricing
  • Docs
  • Log in
Log in
Sign up
Get a demo

Solutions

Extract the data without the plumbing.

Most of the web doesn't have an API. Browserbase gives you real, headless browsers that handle dynamic content, bot detection, and auth, so your pipeline stays running instead of breaking on a Friday night.
Get startedGet a demo

Data extraction that doesn't fight the web.

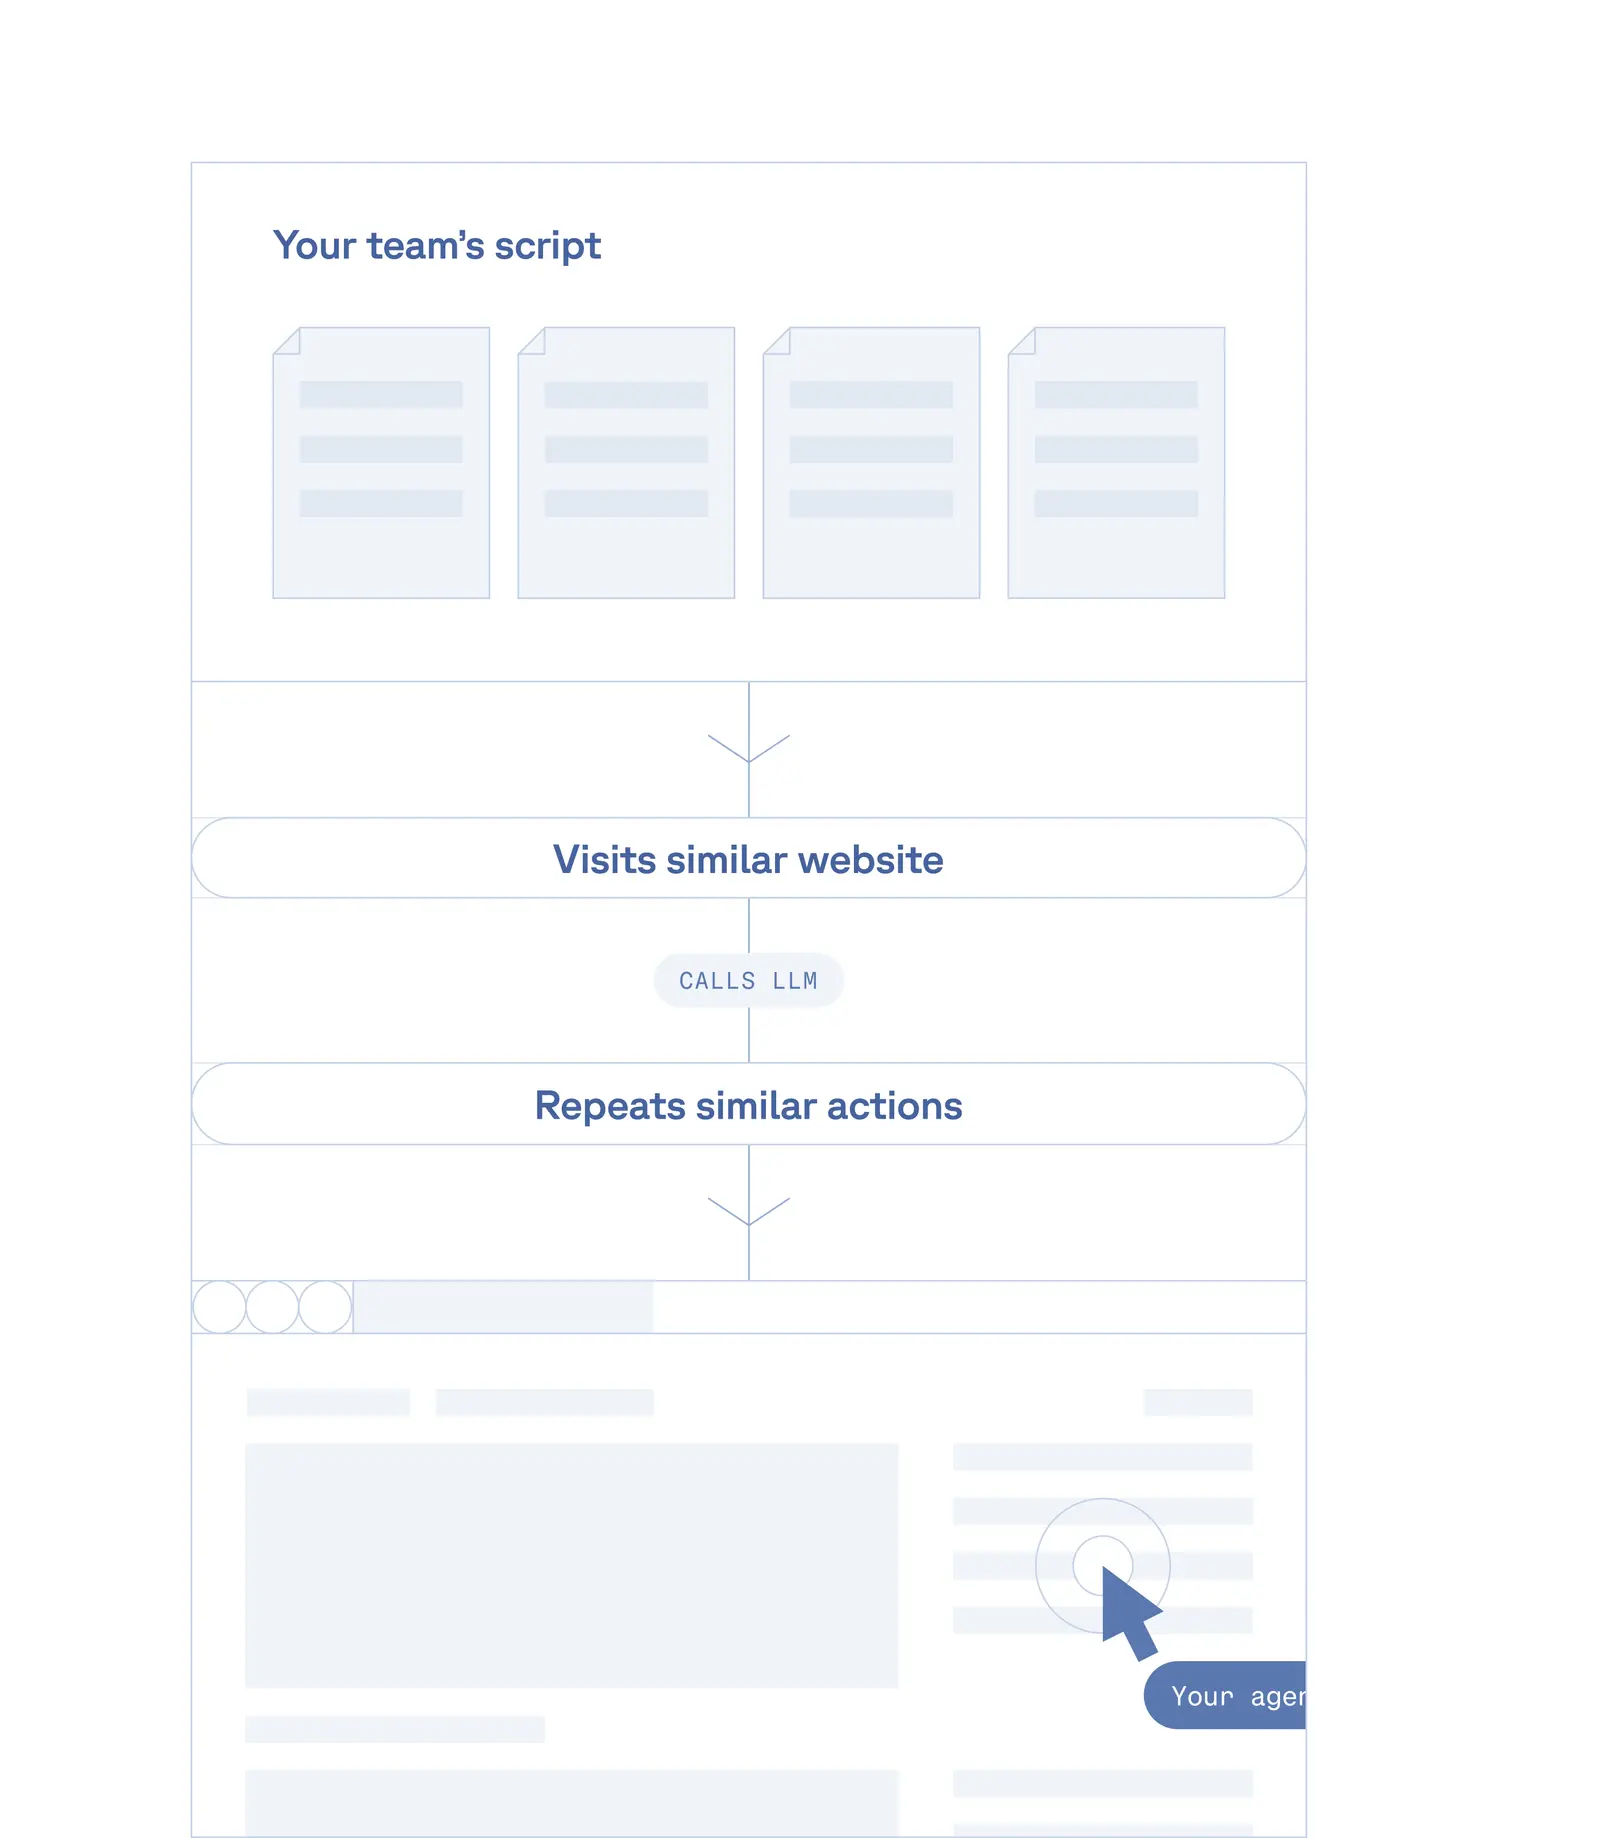
Brittle scripts, blocked requests, broken selectors, sessions timing out. Most data pipelines fail not because the logic is wrong, but because the browser layer can't keep up. Browserbase replaces the fragile parts with real headless browsers that render JavaScript, persist sessions, and bypass bot detection, out of the box. Works with Playwright, Puppeteer, Selenium, or Stagehand.

The data you need isn't waiting behind a clean API.

  • Render everything.

    JS-heavy sites, SPAs, iframes, it all loads correctly.

  • Stay unblocked.

    Built-in stealth handles bot detection and CAPTCHAs.

  • Stay logged in.

    Sessions persist across runs without re-auth overhead.

  • Stop patching.

    Scrapers survive UI changes without script rewrites.

  • Scale without ceremony.

    Run thousands of parallel sessions on demand.

If the data lives on a webpage, you can get it.

Built for teams that need to:

  • Monitor competitor pricing, inventory, or content at scale
  • Enrich leads or company records from public web sources
  • Pull structured data from portals, directories, or dashboards that expose no API
  • Feed AI workflows with fresh, real-world data on a continuous basis

Or start with a template:

  • Extract e-commerce product data, prices, and reviews
  • Extract trending keywords from Google Trends
  • Pull company data from websites for lead enrichment
Browse all templates

Extract at scale. Sleep at night.

SOC 2 Type II certified

Full session isolation, no data bleed between runs
Replaces unreliable legacy tools and self-managed browser clusters

It's good to have someone reliable handling the browser management and CDN challenges so we can focus on the intelligence layer.

Your data pipeline deserves better infrastructure.

Get started freeTalk to us
Browserbase

Primitives

  • Browsers
  • Web APIs
  • Runtime
  • Identity
  • Model Gateway
  • Observability
  • Stagehand
  • MCP

Industries

  • AI
  • Healthcare
  • GTM
  • Tax
  • Legal

Developers

  • Docs
  • Templates
  • APIs & SDKs
  • Changelog
  • Status
  • Github

Company

  • Careers
  • Customers
  • Partner with Us
  • Trust & Security

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service