Skip to content
Browserbase
    • Primitives
      • BrowsersCloud browsers for your agent to use the web
      • AgentsScale fully managed browser agents with simple prompts
      • SearchFind relevant websites from a single query
      • FetchRetrieve web data as agent-ready HTML, JSON, or markdown
      • RuntimeScalable, sandboxed environments for agent deployments
      • IdentityAuthenticate your agent to navigate the web like a human
      • ModelsUse any model with a single API key
      • ObservabilityUnified debugging your agent across replays, logs, and prompts
    • Open Source
      • Browse CLIGive your agent browsing skills with a single command
      • StagehandThe most popular AI browser automation framework
    • Use Cases
      • Browser Agents
      • Automated Testing
      • Workflow Automation
      • Web Data Extraction
      All use cases
    • Industries
      • AI & Agent Platforms
      • Healthcare
      • Fintech
      • GTM
      • Legal
    • Resources
      • Blog
      • Customers
      • Enterprise
      • Templates
  • Pricing
  • Docs
  • Log in
Log in
Sign up
Get a demo

Playwright web scraping that doesn't break

The web wasn't built for agents. Browserbase gives your Playwright scrapers real cloud browsers that render JavaScript, reach pages that turn away ordinary tooling, and return structured data. Keep your existing Playwright scripts, or add the Stagehand SDK for AI-driven extraction.
Get Started
Playwright scraper code alongside a browser interface

The Problem

Why Playwright web scraping breaks in production

  • Running headless Chromium at scale means provisioning and babysitting your own browser fleet.
  • CSS selectors and XPath break every time a site changes its layout.
  • Scripted browser sessions get blocked within minutes by anti-bot systems.
  • Rotating proxies, headers, and CAPTCHAs eat more time than the scraper itself.
  • A local Playwright install fingerprints differently from a real user, so pages turn it away.
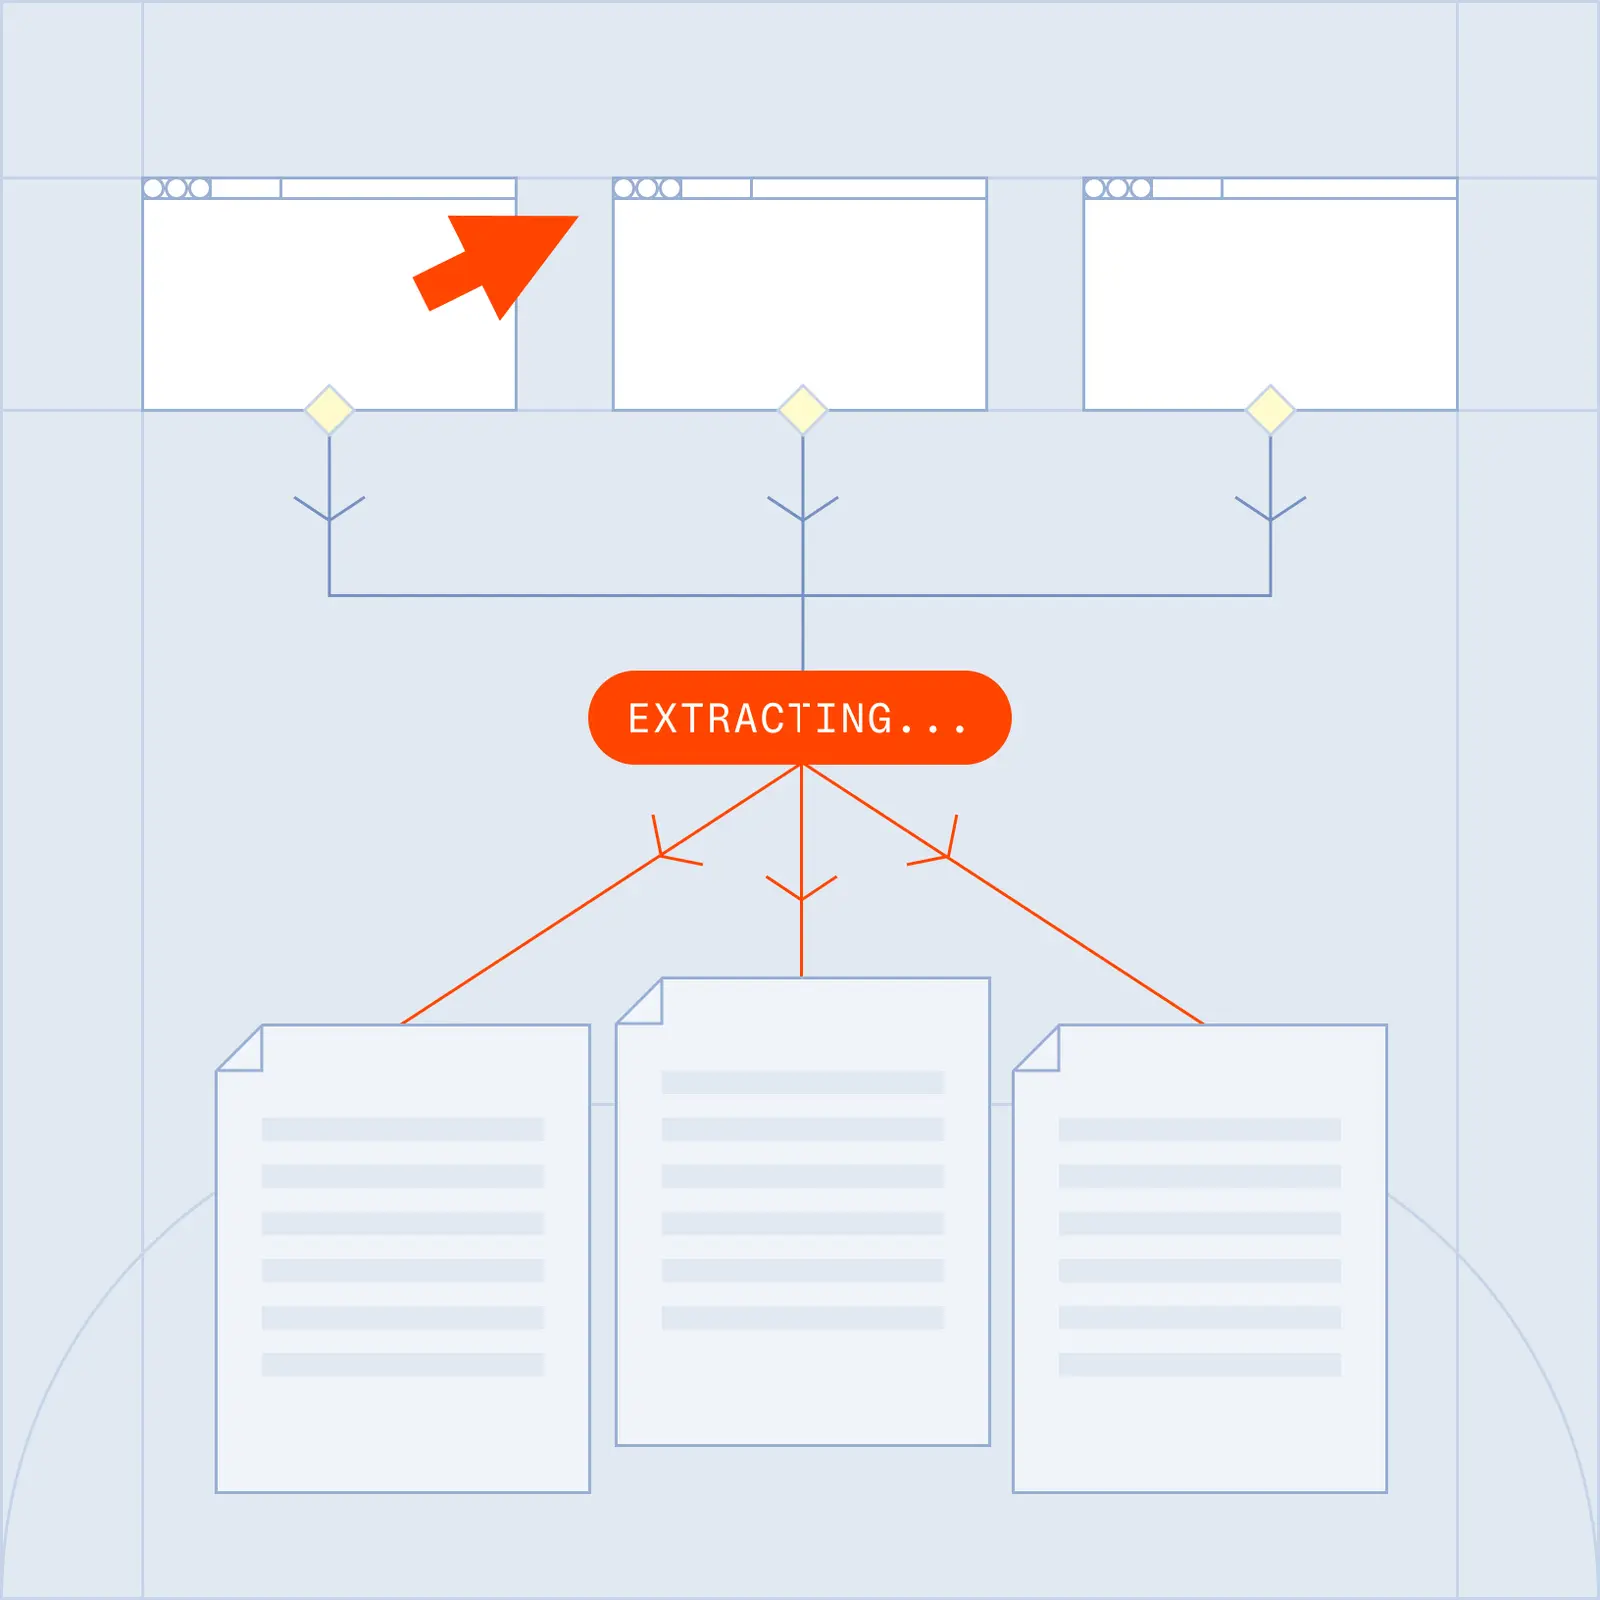
Structured data extracted from a web page

The Solution

How Browserbase changes Playwright web scraping

  • Managed cloud browsers: connect your Playwright script over CDP and run full Chromium sessions in the cloud, with no fleet to provision.
  • Drop-in compatibility: point chromium.connectOverCDP() at a Browserbase session and your existing Playwright code runs unchanged.
  • Natural language extraction: add the Stagehand SDK to describe the data you need and get structured output back, no selectors to maintain.
  • Self-healing selectors: when a site changes its layout, AI re-identifies the right elements automatically.
  • Verified: every session reaches pages that turn away ordinary tooling, with residential proxies and managed CAPTCHA solving included.
  • Agent Identity: Web Bot Auth signs your agent's requests, so sites can verify it instead of guessing.
  • Parallel at scale: run thousands of Playwright sessions simultaneously in the cloud.

What you can build with Playwright

Price and product monitoring

Track pricing, catalogs, and availability across hundreds of sites from a single Playwright job.

Lead enrichment

Extract company details and firmographic data from business directories into your pipeline.

Content and review aggregation

Collect articles, reviews, and user-generated content from dynamic, JavaScript-heavy sources.

Research datasets

Gather data from public records, academic portals, and government databases at scale.

Frequently Asked Questions

What is Playwright web scraping?

Playwright web scraping uses the Playwright browser automation library to control a real browser and extract data from websites. Because Playwright drives full Chromium, Firefox, or WebKit, it renders JavaScript that static tools miss. Browserbase runs those browsers in the cloud and pairs them with the Stagehand SDK for AI-driven extraction.

How do I run Playwright scrapers with Browserbase?

Browserbase runs standard browsers over CDP, so you connect with chromium.connectOverCDP() and your existing Playwright scripts run in the cloud unchanged, with no browser fleet to manage.

Can I use Playwright in Python and TypeScript?

Yes. Browserbase works with Playwright in both Python and Node/TypeScript, plus the Stagehand SDK for natural-language extraction in either language.

How does my Playwright scraper reach pages that block ordinary tooling?

Every session includes Verified access, which manages fingerprints and cookies so your scraper reaches pages that turn away ordinary tooling. Residential proxies route traffic through real IP addresses, and managed CAPTCHA solving covers common challenge types. Agent Identity is the layer above: Web Bot Auth signs your agent's requests so sites can verify it, and we work with bot protection providers rather than evading them.

Can I get structured data out in a specific format?

Yes. With Stagehand you define a schema and the AI returns data matching that exact structure, so you get clean, typed output ready for your database or API with no post-processing.

Can I run Playwright scrapers in parallel?

Yes. Browserbase runs thousands of concurrent browser sessions in the cloud, so you can parallelize a Playwright scrape across many pages or sites at once without provisioning any infrastructure.

What will you build?

Get StartedGet Started
Browserbase

Primitives

  • Browsers
  • Web APIs
  • Runtime
  • Identity
  • Model Gateway
  • Observability
  • Stagehand
  • MCP

Industries

  • AI
  • Healthcare
  • GTM
  • Tax
  • Legal

Developers

  • Docs
  • Templates
  • APIs & SDKs
  • Changelog
  • Status
  • Github

Company

  • Careers
  • Customers
  • Partner with Us
  • Trust & Security

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service