Skip to content
Browserbase
    • Primitives
      • BrowsersCloud browsers for your agent to use the web
      • AgentsScale fully managed browser agents with simple prompts
      • SearchFind relevant websites from a single query
      • FetchRetrieve web data as agent-ready HTML, JSON, or markdown
      • RuntimeScalable, sandboxed environments for agent deployments
      • IdentityAuthenticate your agent to navigate the web like a human
      • ModelsUse any model with a single API key
      • ObservabilityUnified debugging your agent across replays, logs, and prompts
    • Open Source
      • Browse CLIGive your agent browsing skills with a single command
      • StagehandThe most popular AI browser automation framework
    • Use Cases
      • Browser Agents
      • Automated Testing
      • Workflow Automation
      • Web Data Extraction
      All use cases
    • Industries
      • AI & Agent Platforms
      • Healthcare
      • Fintech
      • GTM
      • Legal
    • Resources
      • Blog
      • Customers
      • Enterprise
      • Templates
  • Pricing
  • Docs
  • Log in
Log in
Sign up
Get a demo

Web data extraction without the breakage

The web was not built for agents. Browserbase runs real cloud browsers that extract structured data from any website: Verified access, JavaScript rendering, and AI parsing turn messy pages into clean JSON, ready for your pipeline. Built on infrastructure that runs 35m+ browser sessions a month.
Get a Demo
Browser blocked while extracting data

The Problem

Why web data extraction breaks at scale

  • Brittle CSS and XPath selectors that snap the moment a site ships a layout change.
  • Pages rendered entirely in JavaScript that simple HTTP requests cannot parse.
  • Anti-bot detection that flags your crawlers and burns through proxies.
  • Login walls, captchas, and rate limits that stop your extraction job mid-run.
  • Hours spent maintaining scrapers instead of using the data you came for.
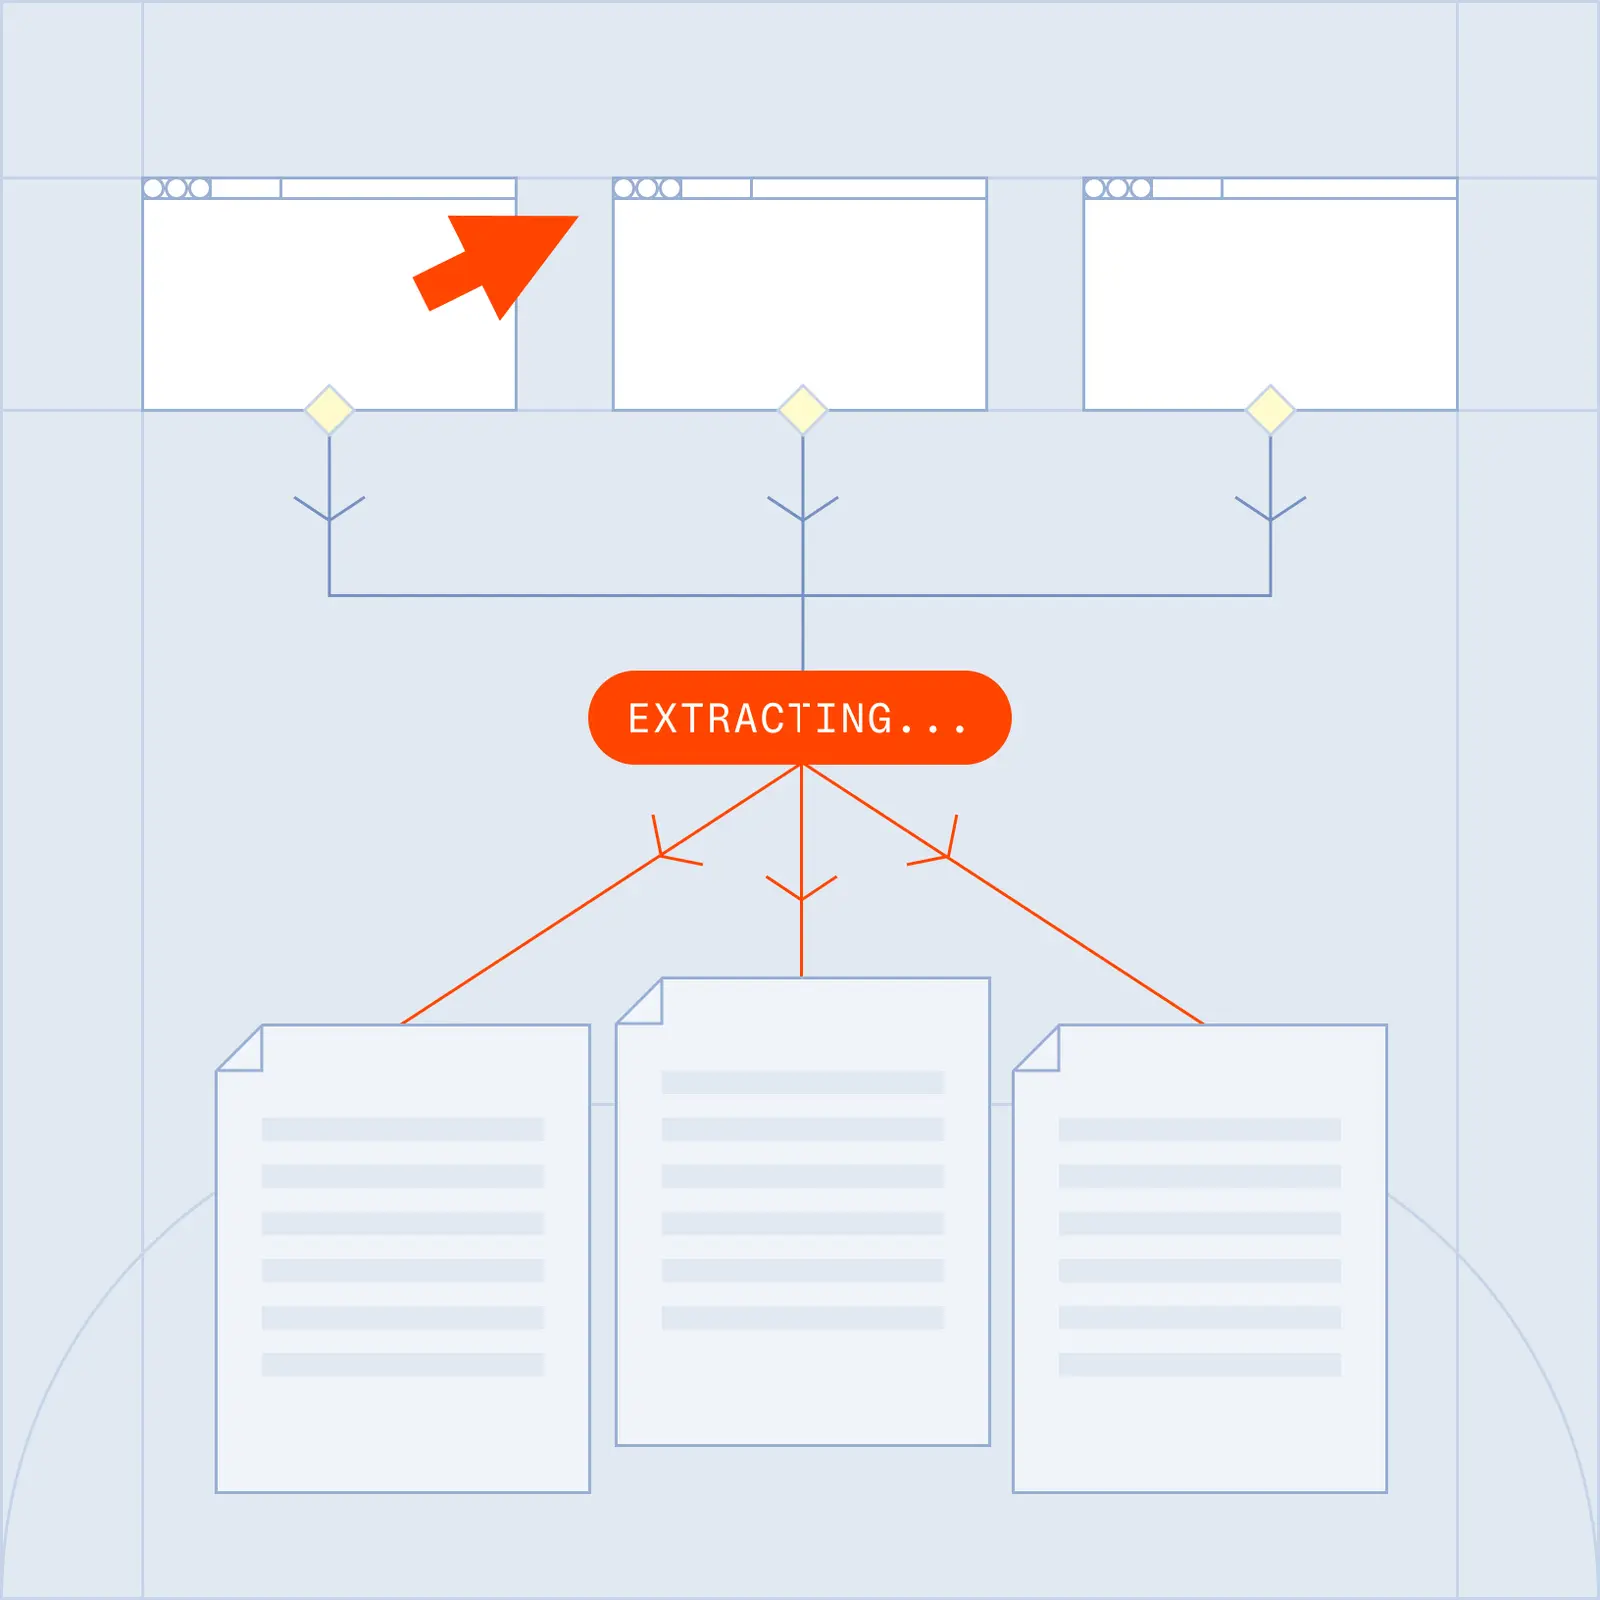
Structured data extracted from web pages

The Solution

How Browserbase powers reliable web data extraction

  • Real cloud browsers: navigate any website the way a human would, with full JavaScript rendering.
  • Verified: reach pages that turn away ordinary tooling, with managed CAPTCHA solving and no proxy burn.
  • Agent Identity: Web Bot Auth signs your agent's requests, so sites can verify it instead of guessing.
  • AI-driven parsing: describe the data you want in plain language with Stagehand®, and get typed output.
  • Persistent contexts: stay logged in to gated sites across extraction runs.
  • Parallel sessions: extract from thousands of pages at once with concurrent browsers.

What you can extract

Product and pricing data

Catalogs, prices, inventory, and specs from ecommerce and B2B storefronts.

Company and contact data

Firmographics, employee counts, leadership, and contact details from public profiles.

Market and financial data

Filings, indices, market signals, and alternative data from public portals.

Content and reviews

Articles, listings, reviews, and ratings from any public-facing website.

Frequently Asked Questions

What is web data extraction?

Web data extraction is the process of pulling structured information from websites and turning it into a usable format like JSON, CSV, or a database row. It powers competitive intelligence, lead generation, price monitoring, market research, and AI training pipelines. Modern web data extraction relies on real browsers, because most sites render content in JavaScript and were never built for automated access.

How is Browserbase different from traditional web data extraction tools?

Traditional tools rely on HTTP requests and hard-coded selectors that break when sites change. Browserbase runs real Chrome browsers in the cloud, so every page renders exactly like it does for a human user. Pair that with Stagehand for AI-driven parsing and you get extraction that adapts to layout changes, handles dynamic content, and avoids the brittle maintenance cycle of legacy scrapers.

Can I extract data from sites that block bots?

Yes. Browserbase includes Verified access, residential proxies, and managed CAPTCHA solving for common challenge types. Real browser fingerprints and isolated sessions let extraction jobs reach pages that turn away traditional scrapers. Agent Identity adds Web Bot Auth signed requests, so sites can verify your agent instead of guessing.

How do I extract structured data without writing brittle selectors?

Use Stagehand, Browserbase’s AI browser automation framework. You describe the data you want in plain English and pass a schema, and the Stagehand SDK returns typed, structured output. When a site changes, the AI adapts. No selector maintenance, no broken pipelines.

Can I extract data behind logins?

Yes. Browserbase Contexts let you persist cookies, localStorage, and session state across runs. Sign in once, save the context, and reuse it on every extraction job without triggering MFA or login walls.

How do I scale web data extraction to thousands of pages?

Run sessions in parallel. Browserbase scales to thousands of concurrent browser sessions on demand, so a one-page extraction script becomes a fleet-wide data pipeline without infrastructure work on your end.

What data formats does Browserbase output?

Whatever you need. The Stagehand SDK returns typed objects you can serialize to JSON, CSV, or write directly to your warehouse. Combine that with Browserbase’s Fetch API, downloads, and screenshots, and you can capture text, structured records, files, and visual snapshots from the same run.

What will you build?

Get a DemoGet Started
Browserbase

Primitives

  • Browsers
  • Web APIs
  • Runtime
  • Identity
  • Model Gateway
  • Observability
  • Stagehand
  • MCP

Industries

  • AI
  • Healthcare
  • GTM
  • Tax
  • Legal

Developers

  • Docs
  • Templates
  • APIs & SDKs
  • Changelog
  • Status
  • Github

Company

  • Careers
  • Customers
  • Partner with Us
  • Trust & Security

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service